AIXX Pedia › Model Entry › NVIDIA RTX 4080 SUPER
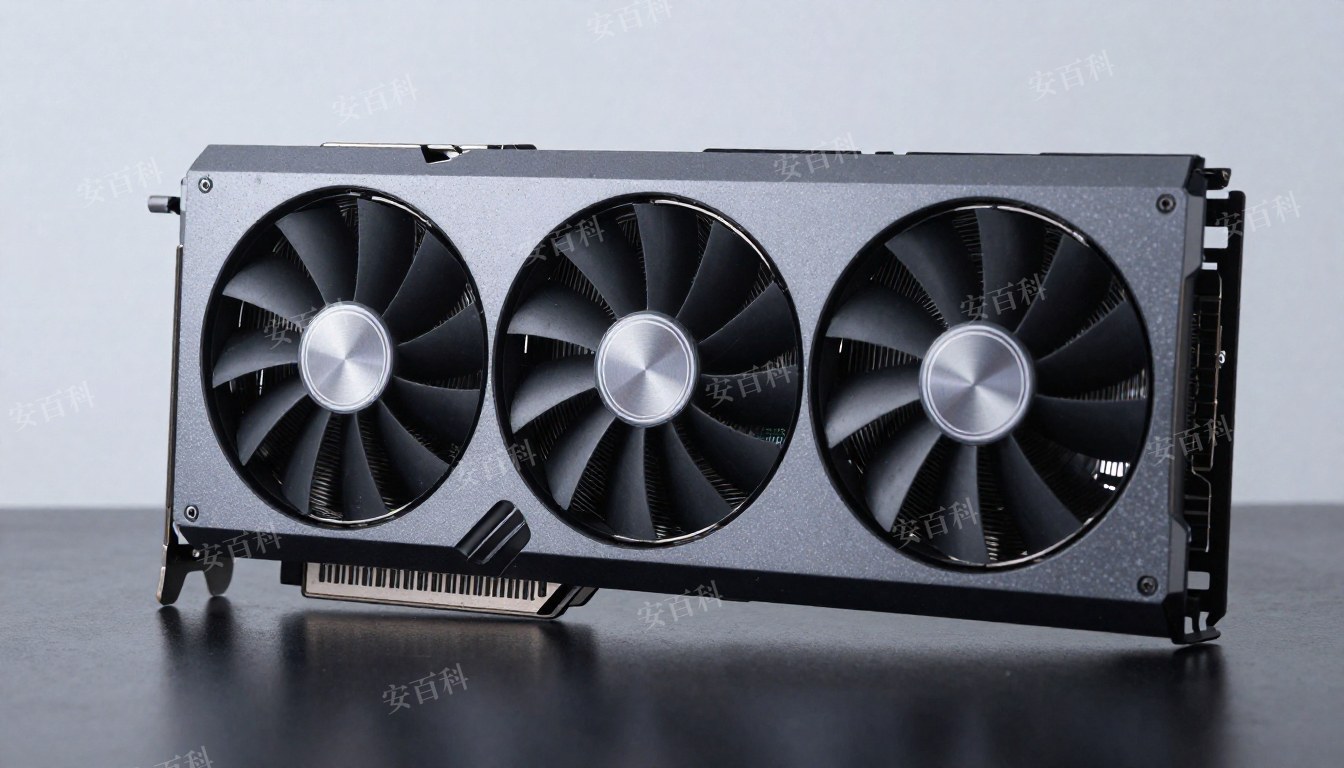
NVIDIA RTX 4080 SUPER
Overview OVERVIEW
RTX 4080 SUPER Belonging to the NVIDIA Ada generation 16GB Speed-Binned Edition (January 2024 launch · official figures): AD103 die, 10240 CUDA 、 16GB GDDR6X · 256-bit 、TGP 320W dual-slot; versus RTX 4080 (9728 CUDA/ 22.4Gbps), core and memory clocks both bumped, and launch price cut in reverse from $1199 to $999 (official launch figures) — among the SUPER trio (4070 Ti SUPER/4080 SUPER, outside the 4090 D line), it sits in the mainstream 4K gaming tier. The Blackwell counterpart slot is filled by RTX 5080 。
History HISTORY
- 2022-11 (official figures for the Ada consumer lineup).
- 2024-01 : the SUPER triple launch (4070 Ti SUPER/4080 SUPER, and the 4090 D China-market Variant released around the same time · official figures), with the 4080 SUPER launching at $999.
- 2024-2025 : the 4080 left the official price list and the SUPER became the mainline 16GB Ada card — Installed-base Circulation is dominated by OEM variants.
- 2025 : RTX 5080 (Blackwell) took over — the 4080 SUPER moved into Installed-base Circulation.
Generation comparison GENERATIONS
| Dimension | RTX 4080 (previous generation · official figures) | RTX 4080 SUPER (this entry · official figures) | RTX 5080 (Blackwell · official figures) |
|---|---|---|---|
| CUDA | 9728 | 10240 | 10752 |
| Memory | 16GB GDDR6X · 22.4Gbps | 16GB GDDR6X · 23Gbps class | 16GB GDDR7 · 960GB/s |
| Bandwidth | ~717GB/s (media figures) | ~737GB/s (media figures) | 960GB/s (official figures) |
| TGP | 320W | 320W | 360W |
| Launch price | $1199 | $999 (official launch figures) | $999 (official launch figures) |
Note: figures = official pages/official launch materials (verified 2026-11); where the official pages do not list bandwidth line-by-line, media figures are noted. AI figures (FP4 TOPS): no same-basis numbers were published for the 40-series, so no direct comparison is made.
Technical Specifications SPECS
| Item | Specs (NVIDIA official) |
|---|---|
| Architecture | Ada Lovelace · AD103 |
| CUDA | 10240 |
| Memory | 16GB GDDR6X · 256-bit (official figures) |
| Power / Form Factor | TGP 320W · dual-slot · 12VHPWR/12V-2x6 power |
| Interface | PCIe 4.0 x16 · DisplayPort 1.4a + HDMI 2.1 |
| Codec | 2× 8th-gen NVENC (dual AV1 encode) + NVDEC (official figures) |
| AI stack | DLSS 3 Frame Generation · 4th-gen Tensor Core (official figures) |
| Launch | 2024-01-31 · $999 (official launch figures) |
Model Fit MODEL FIT
| Use cases | What 16GB GDDR6X can fit (estimate: weights × precision + KV/framework overhead) |
|---|---|
| 7B-14B-class inference | Quantization-feasible, moderate context headroom (estimated basis) |
| 32B class | INT4 Quantization at the limit — barely feasible once KV cache is tightened (estimated basis) |
| Image generation/video | Runs SD/DiT-type workloads smoothly; dual AV1 NVENC gives a clear boost for streaming and editing (ecosystem figures) |
| Training/fine-tuning | Can run LoRA fine-tuning on small models — large-model training is not this tier's use case (physical limits stated as-is) |
Limitations and Boundaries LIMITS
- PCIe 4.0 : usable on PCIe Gen5 platforms at half bandwidth (x16 Gen4 has little impact on most workloads · practical basis).
- Bandwidth generation gap : GDDR6X at ~737GB/s vs GDDR7 at 960GB/s — a noticeable generational gap for inference-throughput-sensitive workloads (official figures compared).
- 12VHPWR wiring : crimping quality of adapters/older cables is one of the main causes of connector burnout (public reporting) — make sure connectors are fully seated when plugging in.