AIXX Pedia › Model Entry › NVIDIA RTX 4070 Ti SUPER
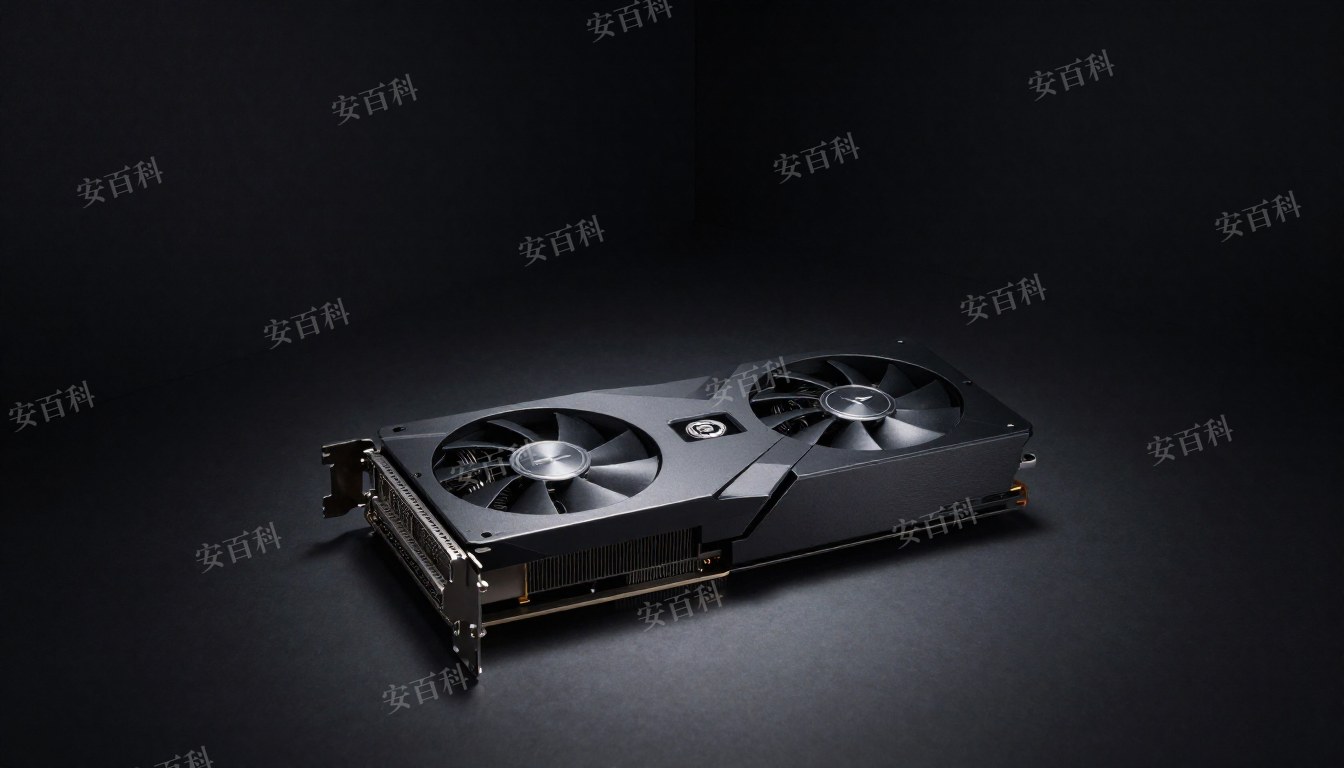
NVIDIA RTX 4070 Ti SUPER
Overview OVERVIEW
RTX 4070 Ti SUPER Belonging to the NVIDIA Ada generation the 16GB big-VRAM sweet spot (Released January 2024 · official figures): AD103 core, 8448 CUDA 、 16GB GDDR6X · 256-bit · 672GB/s 、TGP 285W dual-slot — bringing the 256-bit bus and 16GB of VRAM down to the $799 tier (official launch figures). Significance for AI workloads: for 7B-14B-class quantized inference and image generation, it serves as a low-barrier big-VRAM entry point (estimated figures), with large channel inventory. Its Blackwell-era counterpart is the RTX 5070 Ti 。
History HISTORY
- 2022-11 : RTX 4070 Ti launch (12GB · 192-bit · official figures).
- 2024-01 : The SUPER triple launch — the 4070 Ti SUPER stepped up to 16GB/256-bit at $799 (official launch figures).
- 2024-2026 : The 16GB tier has become the mainstay for both entry-level AI and 2K/4K gaming (market figures) — with continued channel availability.
Generation comparison GENERATIONS
| Dimension | RTX 4070 Ti (previous gen · official figures) | 4070 Ti SUPER (this entry · official figures) | RTX 5070 Ti (Blackwell · official figures) |
|---|---|---|---|
| CUDA | 7680 | 8448 | 8960 |
| Memory | 12GB GDDR6X · 192-bit | 16GB GDDR6X · 256-bit | 16GB GDDR7 · 256-bit |
| Bandwidth | 504GB/s | 672GB/s | 896GB/s |
| TGP | 285W | 285W | 300W |
| AI stack | DLSS 3 | DLSS 3 Frame Generation | DLSS 4 Multi Frame Generation |
Note: all figures = official pages (verified 2026-11). Bandwidth calculated as bus width × effective memory clock per official specs; AI TOPS across the three generations use differing bases (FP4 introduced with the 50 series) and are not directly comparable.
Technical Specifications SPECS
| Item | Specs (NVIDIA official) |
|---|---|
| Architecture | Ada Lovelace · AD103 |
| CUDA | 8448 |
| Memory | 16GB GDDR6X · 256-bit · 672GB/s (official figures) |
| Power / Form Factor | TGP 285W · dual-slot · 12VHPWR/16-pin power |
| Interface | PCIe 4.0 x16 · DisplayPort 1.4a + HDMI 2.1 |
| Codec | AV1 dual NVENC (8th gen · official figures) |
| AI stack | DLSS 3 · 4th-gen Tensor Core (official figures) |
| Launch | 2024-01-31 · $799 (official launch figures) |
Model Fit MODEL FIT
| Use cases | What 16GB GDDR6X can fit (estimate: weights × precision + KV/framework overhead) |
|---|---|
| 7B-14B-class inference | Fits INT4/FP8 quantization — the main entry tier for local LLMs (estimated figures) |
| Image generation/video | Smooth for SD/DiT-class models; 16GB offers clearly more headroom than the 12GB tier for high-resolution generation (estimated figures) |
| Speech/multimodal | Fits multiple instances of Whisper/VLM-class small models (ecosystem figures) |
| Training/fine-tuning | 7B-class LoRA runs on a single card — for larger scale, look at the 24GB+ tier (physical limits, stated as such) |
Limitations and Boundaries LIMITS
- Bus width/bandwidth : 672GB/s trails the GDDR7 generation by roughly 33% — evaluate by the generational gap for throughput-sensitive inference scenarios (official figures, comparison).
- PCIe 4.0 : Friendly to older platforms; not a bottleneck on PCIe 5.0 platforms (x16 4.0 · practical figures).
- 285W power : Single 16-pin connector — size the PSU with headroom for the whole system (pre-deployment · practical figures).